

💜 Built and maintained by one independent developer — no company, no overhead, just code. If SpawnDev.ILGPU saves you time, please consider sponsoring its development ». Sponsorship is what keeps it alive and maintained.
Run ILGPU C# kernels on WebGPU, WebGL, Wasm, Cuda, OpenCL, and CPU - from a single codebase.
Write parallel compute code in C# and let the library pick the best available backend automatically. In the browser, three backends (WebGPU, WebGL, Wasm) bring GPU-accelerated compute to virtually every modern browser. On desktop and server, ILGPU's native Cuda and OpenCL backends are available alongside CPU. The same async extension methods work everywhere.
Your existing ILGPU kernels run in the browser with zero changes to the kernel code - and the same code runs on desktop too.
Unreleased (master): Hybrid GPU machines pick the discrete GPU. CreatePreferredAccelerator(Async) and the new context.GetBestDevice() / DevicePreference.OrderByPreference() rank CUDA > discrete OpenCL GPU > integrated OpenCL GPU > other OpenCL > CPU. Memory size only breaks ties now, because integrated GPUs and Intel's OpenCL CPU runtime report system RAM. In the browser the order is WebGPU > WebGL > Wasm.
5.3.6: Idle GPU memory is reclaimed before the driver spills. On Windows the NVIDIA driver places an allocation that does not fit in system RAM instead of failing it, so a reclaim that waits for a failed allocation never runs. Holders of reclaimable memory (IDeviceMemoryReclaimer, e.g. SpawnDev.ILGPU.ML's buffer pools) register with accelerator.RegisterReclaimer(...), and every allocation then checks free memory first (CUDA) and reclaims least-recently-used memory when the allocation would leave less than DeviceMemoryHeadroomBytes. See Memory & Buffers.
5.3.2 - 5.3.5: Persisted shaders: ShaderArtifactSerializer.ExportCache() / ImportCache(json) carry a session's compiled WebGPU shaders into the next session, and a stored kernel skips ILGPU's IR construction as well as WGSL generation. Faster WGSL compiles, WebGPU batched-dispatch arenas and bind-group reuse, exact subnormal Half decode on the emulated backends, Firefox video-frame copies, a corrected exclusive CreateScan on WebGPU and Wasm past one chunk, device-to-device CopyTo on WebGPU and Wasm, and a Mono WASM AOT fix (no static fields on generic view structs).
5.3.1: Trimming is enforced at library level, and Blazor WebAssembly AOT is supported with the IL kept (RunAOTCompilation=true + WasmStripILAfterAOT=false). bool kernel scalar parameters work on all 6 backends, and float/double % is exact (IEEE fmod) everywhere.
5.3.0: Built on SpawnDev.SpawnJS 3.0 (replaces SpawnDev.BlazorJS as the browser interop layer): every .NET to JS call is one boundary crossing. Host time per unbatched WebGPU dispatch dropped from 251 to 80 us.
5.2.25: WebGPU dispatch batching - plain dispatches, copies, clears and small uploads are recorded and submitted with one .NET to JS crossing per submit (433 -> 41 us host time per dispatch, measured). IExternalImageCopier copies a <video>, <img>, canvas, ImageBitmap or VideoFrame into a GPU buffer, entirely on the GPU on WebGPU (the input-side twin of ICanvasRenderer).
5.2.x: A long correctness series on the browser code generators (loops with breaks, switch, [NoInlining] helpers, short-circuit branches, emulated 64-bit conversions and rounding), Wasm pipelined dispatch, WebGPU live-buffer accounting (WebGPUBufferAccounting), one compute pipeline per kernel instead of one per dispatch size, and the first trim-safe release (5.2.0).
4.x highlights still current: WebGPU dispatch-plan capture/replay (4.17), streaming CopyFromStreamAsync / CopyToStreamAsync (4.9.14 / 4.17), CUDA graph capture (4.16), Wasm SIMD128 auto-vectorization (4.15), the 4-bit / low-precision type tier (4.13 - 4.14), the sync/async contract (4.12) and precompiled shaders (4.10).
See CHANGELOG.md for the full per-version history - every release, code samples, and per-backend implementation detail.
Browser backends (Blazor WebAssembly) - auto-selected: WebGPU -> WebGL -> Wasm
| WebGPU | WebGL | Wasm | |
|---|---|---|---|
| Compiles to | WGSL | GLSL ES 3.0 | Wasm binary |
| Runs on | GPU | GPU | Web Workers |
Desktop backends (Console, WPF, ASP.NET) - auto-selected: Cuda -> discrete OpenCL GPU -> integrated OpenCL GPU -> other OpenCL -> CPU
| Cuda | OpenCL | CPU | |
|---|---|---|---|
| Compiles to | PTX | OpenCL C | - |
| Runs on | NVIDIA GPU | Any GPU | CPU cores |
The Live Demo source is in SpawnDev.ILGPU.Demo:
- Fractal Explorer - Interactive Mandelbrot / Multi-fractal Explorer with double-precision zoom
- 3D Raymarching - Real-time GPU raymarched scenes
- GPU Boids - 3D flocking simulation with GPU physics
- Game of Life - Conway's Game of Life on the GPU
- Benchmarks - Performance comparison across all backends
- Unit Tests - Comprehensive test suite for all backends
The WPF Demo runs the same shared kernels on CUDA, OpenCL, and CPU with live backend switching:
- Fractal Explorer - Interactive Mandelbrot / Multi-fractal Explorer with double-precision zoom
- 3D Raymarching - Real-time GPU raymarched scenes
- GPU Boids - 3D flocking simulation with GPU physics
- Benchmarks - Performance comparison across CUDA, OpenCL, and CPU backends
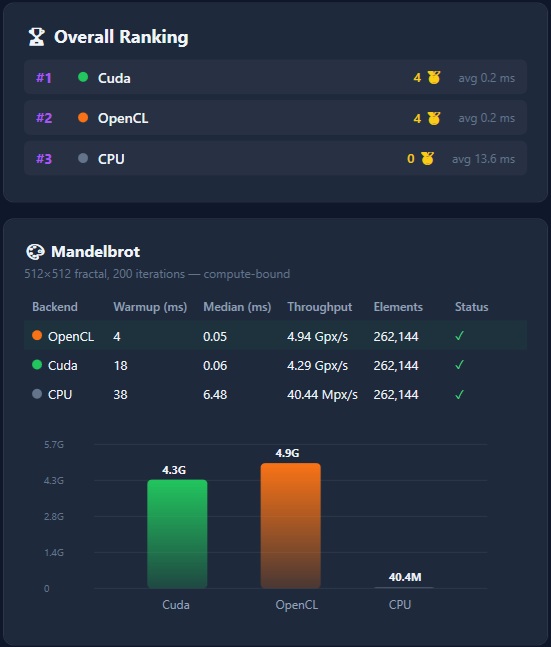
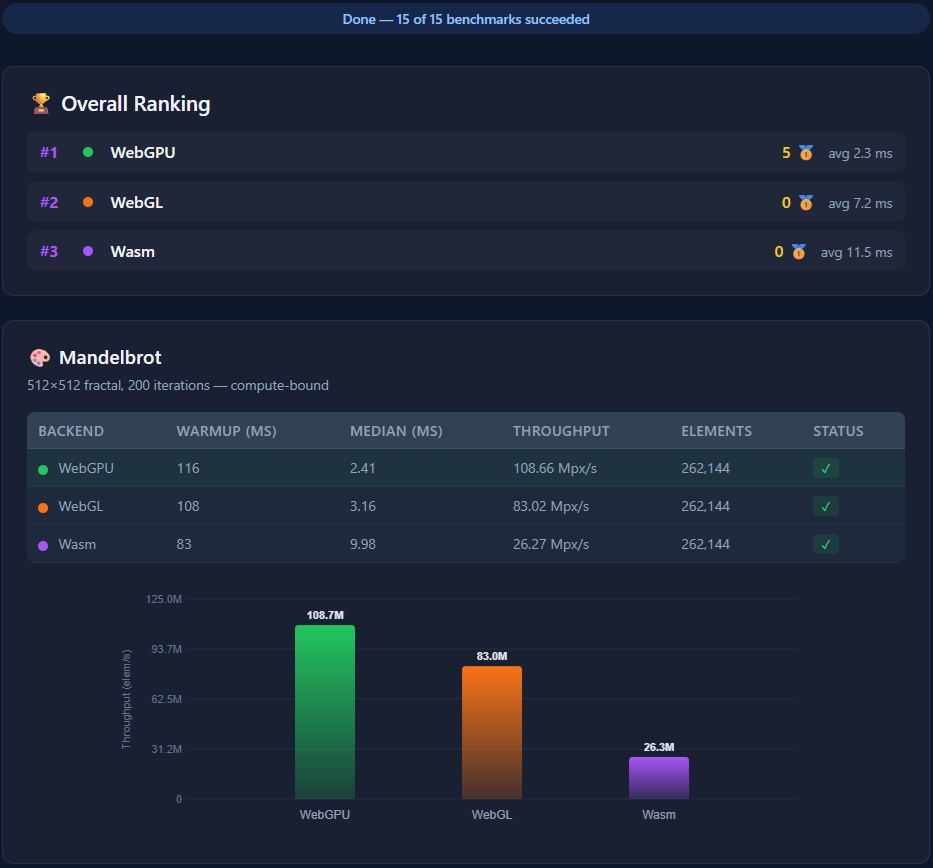
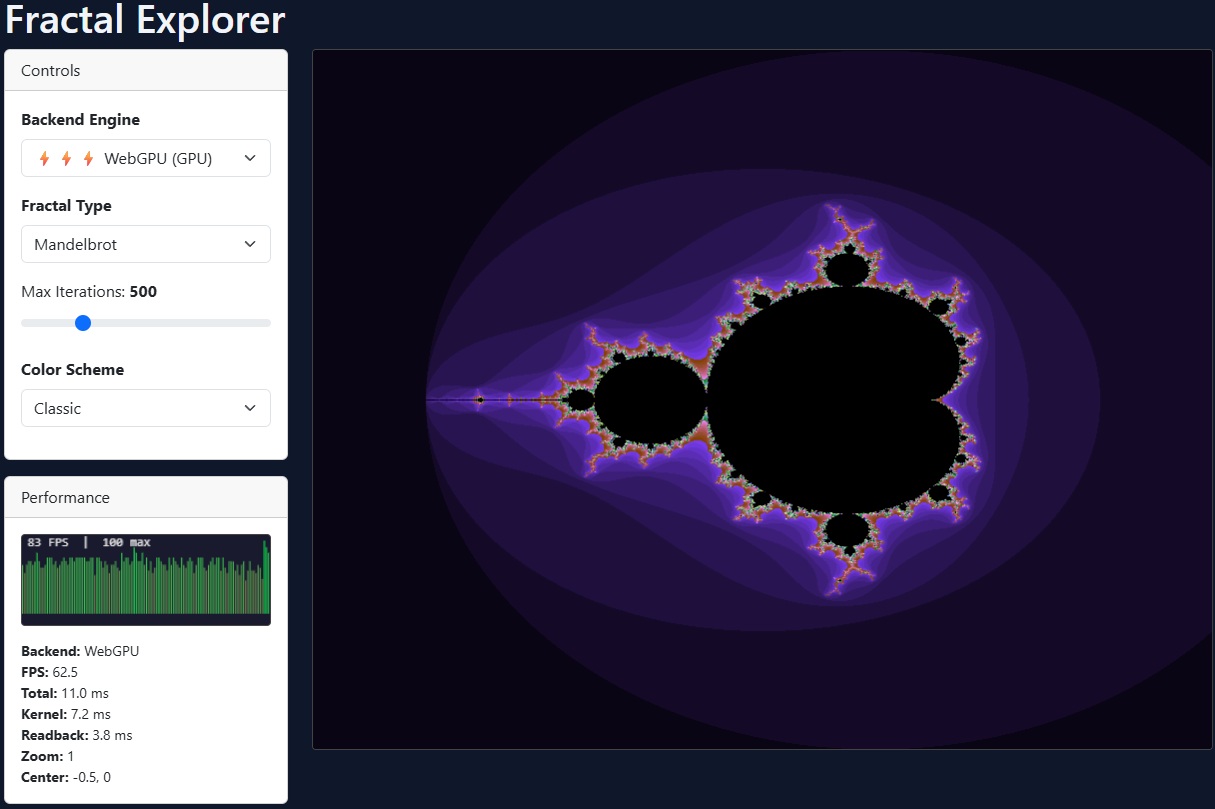
Comprehensive documentation is available in the Docs folder:
- Getting Started - Installation, setup, first kernel
- Backends - WebGPU, WebGL, Wasm, Cuda, OpenCL, CPU setup & configuration
- Writing Kernels - Kernel rules, index types, math functions, shared memory
- Memory & Buffers - Allocation, async readback, zero-allocation patterns
- Data Type Support - Sub-word types (Int8/16), low-precision floats (
Half,BFloat16, FP8Float8E4M3/E5M2, FP4Float4E2M1), packed 4-bit ints (QInt4/QUInt4), 64-bit emulation, per-backend details - Canvas Rendering & Image Input -
ICanvasRenderer(GPU buffer -> canvas) andIExternalImageCopier(video / image -> GPU buffer), per-backend details - Capabilities & Backend Selection -
AcceleratorRequirements, device ranking (GetBestDevice),UnsupportedKernelFeatureException - Async API - the sync/async contract: which operations wait or read back (async-only on the browser) and which are fire-and-forget
- Advanced Patterns - Device sharing, external buffers, GPU intrinsics, render loops
- CUDA Libraries - nvJPEG, cuRand, cuBLAS, cuFFT, NVML wrappers
- Limitations - Blazor WASM constraints, browser compatibility
- QR Codes - GPU-accelerated QR code encoder, decoder, renderer with logo overlay
- API Reference - Public API surface by namespace
- Precompiled Shaders - Offline codegen, build-time shader precompilation, runtime cache, and session shader export/import (move IL->shader transpilation off the runtime hot path)
- WebGPU Dispatch-Plan Capture / Replay - Record a fixed WebGPU dispatch sequence once and replay it with a single interop crossing (the browser twin of CUDA graph capture), with a patch surface for parameterized replay
Six backends from one NuGet package - the same C# kernel runs on all of them:
| Browser (Blazor WASM) | Desktop / Server |
|---|---|
| WebGPU (WGSL compute) · WebGL (GLSL Transform-Feedback) · Wasm (multi-worker WebAssembly) | CUDA (PTX) · OpenCL (incl. 3.0) · CPU |
All support the sub-word + low-precision types (Int8/16, Half, BFloat16, FP8 Float8E4M3/E5M2, FP4 Float4E2M1, packed 4-bit ints QInt4/QUInt4), 64-bit (native on Wasm/CUDA/OpenCL/CPU, emulated on WebGPU/WebGL), and the ILGPU Algorithms. Packed 4-bit (Float4E2M1/QInt4/QUInt4) loads on all 6; in-kernel packed stores run on CUDA/OpenCL/WebGPU/Wasm and are fail-loud on CPU + WebGL (no atomics for the nibble RMW). WebGL is the exception - no shared memory / barriers / atomics, so in-kernel group/warp ops throw (host RadixSort/Scan/Reduce still work, all key types). Auto-selection: WebGPU->WebGL->Wasm (browser), CUDA->discrete OpenCL GPU->integrated OpenCL GPU->other OpenCL->CPU (desktop), via CreatePreferredAcceleratorAsync. Full per-backend capability matrix + setup: Docs/backends.md.
- Sub-word & low-precision data types -
Int8,UInt8,Int16,UInt16,Float16(ILGPU.Half),BFloat16, FP8 (Float8E4M3+Float8E5M2), FP4 (Float4E2M1, the NVFP4/MXFP4 element format), and packed 4-bit integersQInt4/QUInt4- buffer access on all 6 backends, each a realBasicValueTypeIR primitive (the float types with fullINumber<T>support).BFloat16keeps fp32's full dynamic range (top 16 bits of an fp32); FP8 is 1-byte in the two OCP formats (E4M3 forward/inference bit-exact tofloat8_e4m3fn, E5M2 backward/gradient). The 4-bit types (Float4E2M1/QInt4/QUInt4) are TRUE packed 4-bit - 2 nibbles/byte,ceil(N/2)bytes - decoded to f32 in-register at the load (the data stays packed in the buffer); radix-sort and<Type>Extensions.RawBitsToFloat(int)(kernel-safe in-register decode of raw packed quant bits) are provided.Half.Abs/Min/Max/Clampintrinsics;Halffloat→half andFloat8E4M3are IEEE/ml_dtypes bit-exact across every backend - Generic mixed-precision kernels - one
where T : INumber<T>kernel runs for float/Half/bf16/fp8 instead of N hand-written per-type variants;PrecisionConvert.ConvertToSingle<T>/ConvertFromSingle<T>give transpilable genericfloat<->Tconversion inside a kernel (read low-precision, accumulate in float, write low-precision) - WebGPU dispatch-plan capture / replay - Record a fixed sequence of WebGPU dispatches once (
BeginDispatchCapture()/EndDispatchCapture()->WebGPUDispatchPlan), thenReplayAsync()re-encodes and submits the whole plan with a single .NET->JS interop crossing - the browser twin of CUDA graph capture, removing the per-dispatch orchestration cost of a fixed-shape forward. A patch surface (CaptureScalarSnapshots,PatchScalarInt,PatchCopyDstOffsetsAsync) replays one plan across a moving loop variable (the LLM decode / KV-append case). See Docs/dispatch-plan-capture-replay.md - CopyFromJS - Write JavaScript
TypedArrayorArrayBufferdata directly to GPU memory without .NET heap allocation. Available on all browser backends - CopyFromStreamAsync / CopyToStreamAsync - Stream a
System.IO.Streaminto a GPU buffer, or a GPU buffer out to aStream, in bounded chunks (all 6 backends). On the browser backends, if the stream implementsIJSReadStream/IJSWriteStream(SpawnDev.SpawnJS.Toolbox), the bytes move JS↔GPU without entering the .NET/WASM managed heap - load a multi-hundred-MB model from aBlob/OPFS or save a large buffer to OPFS with one chunk resident at a time. See Memory & Buffers - Lambda kernels - Write kernels as capturing C# lambdas - captured scalar values are automatically passed to the GPU at dispatch time. No boilerplate, all 6 backends
- Higher-order kernels -
DelegateSpecialization<Func<T,R>>lets you pass operations as kernel parameters. The delegate is resolved and inlined at compile time - one kernel, many behaviors - Cross-platform - Same kernel code runs in browser (WebGPU, WebGL, Wasm) and desktop (Cuda, OpenCL, CPU) from one NuGet package
- Automatic backend selection -
CreatePreferredAcceleratorAsync()picks the best backend on any platform (browser or desktop). On hybrid laptops it picks the discrete GPU (context.GetBestDevice()ranks devices by kind, not by reported memory) - Capability gating - declare what a kernel needs (
AcceleratorRequirements: atomics, shared memory, native f64, packed 4-bit stores, ...) and selection skips backends that cannot run it. See Capabilities & Backend Selection - Device memory budget - holders of idle device memory implement
IDeviceMemoryReclaimerand register with the accelerator; allocations reclaim least-recently-used memory before the device runs out (and before the NVIDIA driver silently spills to system RAM) - WebGPU dispatch batching - dispatches, GPU copies, clears and small uploads are recorded and submitted with one .NET to JS crossing per submit; bind groups and scalar uploads are reused across repeated dispatch sequences
- Unified async API -
SynchronizeAsync(),CopyToHostAsync(), andCopyFromAsync()work everywhere, falling back to synchronous calls on desktop - ILGPU-compatible - Use familiar APIs (
ArrayView,Index1D/2D/3D, math intrinsics, etc.) - WGSL transpilation - C# kernels automatically compiled to WebGPU Shading Language
- GLSL transpilation - C# kernels compiled to GLSL ES 3.0 vertex shaders with Transform Feedback for GPU compute
- Wasm compilation - C# kernels compiled to native WebAssembly binary modules
- 64-bit emulation -
long/ulong(i64) always emulated viavec2<u32>(required by ILGPU IR).double(f64) emulation configurable viaF64EmulationMode: fast Dekker (vec2<f32>, default), precise Ozaki (vec4<f32>), or Disabled (promoted to f32) - WebGPU extension auto-detection - Probes adapter for
shader-f16,subgroups,timestamp-query, and other features; conditionally enables them on the device - Subgroup operations -
Group.BroadcastandWarp.Shuffle/ShuffleXor/ShuffleUp/ShuffleDownrun on WebGPU when the adapter exposes thesubgroupsfeature, and on Wasm through an emulation (WarpSize8, shared-memory exchange) - Multi-worker dispatch - Wasm backend distributes work across all available CPU cores via SharedArrayBuffer; falls back to a single off-thread worker when SAB is unavailable
- Pipelined Wasm dispatch - worker scripts are cached per kernel shape (per-dispatch values travel in the message, never in the script), compiled modules stay cached in persistent workers, and small barrier-free dispatches are pipelined (the host prepares dispatch N+1 while a worker runs dispatch N, results identical to the serialized path)
- Zero-copy canvas rendering -
ICanvasRendererpresents pixel buffers to HTML canvases without CPU readback on GPU backends: WebGPU uses a fullscreen-triangle render pass reading directly from GPU storage; WebGL transfers anImageBitmapfrom its worker and draws synchronously; Wasm reuses a cachedImageData. One API, all backends:CanvasRendererFactory.Create(accelerator) - Video / image input -
IExternalImageCopier(ExternalImageCopier.Create(accelerator)) copies a<video>,<img>, canvas,ImageBitmap,VideoFrameorImageDatainto a GPU buffer as packed RGBA8, the same layoutICanvasRendererpresents. On WebGPU it never leaves the GPU (copyExternalImageToTexture+copyTextureToBuffer) - Blazor WebAssembly - Browser interop via SpawnDev.SpawnJS (one boundary crossing per .NET to JS call)
- Shared memory & barriers - Static and dynamic workgroup memory with
Group.Barrier()synchronization (WebGPU, Wasm, Cuda, OpenCL) - ILGPU Algorithms - RadixSort, Scan, Reduce, Histogram, and other algorithm extensions are fully supported on WebGPU (including large-scale sorts up to 4M+ elements) and Wasm (with multi-worker barrier synchronization), tested in-browser across all backends. Radix-sort (keys + key/value pairs, ascending + descending) covers every key type -
int/uint/long/float/doubleplusHalf,BFloat16, FP8, FP4 (Float4E2M1), and packedQInt4/QUInt4. WebGL supports host-levelRadixSort(up to 4M elements),CreateScan, andCreateReduction/Reducevia shared-memory-free multi-dispatch emulation (the draw-call boundary is the barrier); in-kernel group/warp ops throw a typed error since the Transform-Feedback vertex model has no shared memory - Broadcast -
Group.Broadcastfor intra-group value sharing (WebGPU, Wasm) - Device loss handling - WebGPU monitors
device.lostand WebGL monitorswebglcontextlost;IsDeviceLost/IsContextLostproperties andDeviceLost/ContextLostevents enable applications to detect GPU device loss and fail fast with clear errors instead of silent corruption - GpuMatrix4x4 - GPU-friendly 4x4 matrix struct that auto-transposes from .NET's row-major
Matrix4x4to GPU column-major order. UseTransformPointandTransformDirectiondirectly inside kernels for 3D transformations - No native dependencies - Entirely written in C#
dotnet add package SpawnDev.ILGPUSpawnDev.ILGPU uses SpawnDev.SpawnJS for browser interop (it comes in as a dependency). Register the runtime and start the app with SpawnJSRunAsync() from the Blazor host package:
dotnet add package SpawnDev.SpawnJS.Blazorusing SpawnDev.SpawnJS;
var builder = WebAssemblyHostBuilder.CreateDefault(args);
builder.RootComponents.Add<App>("#app");
builder.RootComponents.Add<HeadOutlet>("head::after");
// Add the SpawnJS runtime (required for the browser backends)
builder.Services.AddSpawnJSRuntime();
// Starts SpawnJS background services, then the Blazor host
await builder.Build().SpawnJSRunAsync();Coming from SpawnDev.ILGPU 5.2 or older:
AddBlazorJSRuntime()/BlazorJSRunAsync()becameAddSpawnJSRuntime()/SpawnJSRunAsync(), andSpawnDev.BlazorJS.JSObjectstypes (HTMLCanvasElement,Uint8Array, ...) live inSpawnDev.SpawnJS.JSObjects. Build clean (deletebinandobj) after upgrading.
The library discovers all available browser backends and picks the best one (WebGPU -> WebGL -> Wasm):
using global::ILGPU;
using global::ILGPU.Runtime;
using SpawnDev.ILGPU;

// Initialize context with all available backends
using var context = await Context.CreateAsync(builder => builder.AllAcceleratorsAsync());

// Create the best available accelerator (WebGPU > WebGL > Wasm)
using var accelerator = await context.CreatePreferredAcceleratorAsync();

// Allocate buffers and run a kernel - same API regardless of backend
int length = 256;
using var bufA = accelerator.Allocate1D(Enumerable.Range(0, length).Select(i => (float)i).ToArray());
using var bufB = accelerator.Allocate1D(Enumerable.Range(0, length).Select(i => (float)i * 2f).ToArray());
using var bufC = accelerator.Allocate1D<float>(length);

var kernel = accelerator.LoadAutoGroupedStreamKernel<Index1D, ArrayView<float>, ArrayView<float>, ArrayView<float>>(VectorAddKernel);
kernel((Index1D)length, bufA.View, bufB.View, bufC.View);

await accelerator.SynchronizeAsync();
var results = await bufC.CopyToHostAsync<float>();

// The kernel - runs on GPU or Wasm transparently
static void VectorAddKernel(Index1D index, ArrayView<float> a, ArrayView<float> b, ArrayView<float> c)
{
    c[index] = a[index] + b[index];
}// WebGPU - GPU compute via WGSL
using var context = await Context.CreateAsync(builder => builder.WebGPU());
var device = context.GetWebGPUDevices()[0];
using var accelerator = await device.CreateAcceleratorAsync(context);// WebGL - GPU compute via GLSL ES 3.0 + Transform Feedback (works on virtually all browsers)
using var context = await Context.CreateAsync(builder => builder.WebGL());
var device = context.GetWebGLDevices()[0];
using var accelerator = await device.CreateAcceleratorAsync(context);// Wasm - native WebAssembly binary
using var context = await Context.CreateAsync(builder => builder.Wasm());
var device = context.GetDevices<WasmILGPUDevice>()[0];
using var accelerator = await device.CreateAcceleratorAsync(context);SpawnDev.ILGPU also works in console, WPF, ASP.NET, and other .NET apps. The same async pattern used in Blazor WASM works on desktop too:
using global::ILGPU;
using global::ILGPU.Runtime;
using SpawnDev.ILGPU;

// SAME code as Blazor WASM - AllAcceleratorsAsync auto-detects the environment
// Browser: registers WebGPU, WebGL, Wasm (+ ILGPU's CPU accelerator as a last resort)
// Desktop: registers Cuda, OpenCL, CPU (browser backends are skipped)
using var context = await Context.CreateAsync(builder => builder.AllAcceleratorsAsync());
using var accelerator = await context.CreatePreferredAcceleratorAsync();

Console.WriteLine($"Using: {accelerator.Name} ({accelerator.AcceleratorType})");

// Same kernel code, same async extensions
int length = 256;
using var bufA = accelerator.Allocate1D(Enumerable.Range(0, length).Select(i => (float)i).ToArray());
using var bufB = accelerator.Allocate1D(Enumerable.Range(0, length).Select(i => (float)i * 2f).ToArray());
using var bufC = accelerator.Allocate1D<float>(length);

var kernel = accelerator.LoadAutoGroupedStreamKernel<Index1D, ArrayView<float>, ArrayView<float>, ArrayView<float>>(VectorAddKernel);
kernel((Index1D)length, bufA.View, bufB.View, bufC.View);

// SynchronizeAsync/CopyToHostAsync fall back to synchronous calls on desktop
await accelerator.SynchronizeAsync();
var results = await bufC.CopyToHostAsync<float>();

Console.WriteLine($"result[0]={results[0]}, result[255]={results[255]}");

static void VectorAddKernel(Index1D index, ArrayView<float> a, ArrayView<float> b, ArrayView<float> c)
{
    c[index] = a[index] + b[index];
}
Same kernel, any platform. The
VectorAddKernelabove is identical in both examples. Write once, run on WebGPU, WebGL, Wasm, Cuda, OpenCL, or CPU.
Why async? Browser backends require async - Blazor WASM's single-threaded environment will deadlock on synchronous calls. Desktop backends support both sync and async, with async extensions gracefully falling back to synchronous ILGPU calls. Therefore, the async pattern is always recommended for maximum portability.
All desktop and browser tests run in a single dotnet test invocation via the PlaywrightMultiTest NUnit project:
# Run all tests (desktop + browser) with timestamped results
timestamp=$(date +%Y%m%d_%H%M%S) && dotnet test PlaywrightMultiTest/PlaywrightMultiTest.csproj \
  --logger "trx;LogFileName=results_${timestamp}.trx" \
  --results-directory PlaywrightMultiTest/TestResults

# Scope a run: PMT_FILTER is a comma-separated list of substrings matched against the
# test name, class and method. (dotnet test --filter only narrows what NUnit REPORTS;
# the scheduler still runs everything, so use PMT_FILTER.)
PMT_FILTER=AlgorithmRadixSortPairsTest dotnet test PlaywrightMultiTest/PlaywrightMultiTest.csproj

# Scope by backend: PMT_LANES matches test CLASS names
PMT_LANES=WebGPUTests PMT_FILTER=RadixSort dotnet test PlaywrightMultiTest/PlaywrightMultiTest.csproj
How it works:
- Publishes Blazor WASM and Console projects automatically (the demo publishes TRIMMED, so every run tests the libraries the way consumers ship them)
- Launches Chromium via Playwright for browser tests (with
--enable-unsafe-webgpu) - Runs desktop tests as individual subprocesses, in parallel lanes (CPU, CUDA, OpenCL) next to the browser lane; Wasm runs alone afterwards
- Detects Blazor error UI during tests and captures browser console errors/warnings
- All results surfaced as standard NUnit test cases with
.trxoutput
Start the demo app and navigate to /tests to run the browser test suite interactively:
dotnet run --project SpawnDev.ILGPU.DemoEvery feature is tested on all 6 backends (WebGPU, WebGPU-no-subgroups, WebGL, Wasm, CUDA, OpenCL, CPU) through the unified PlaywrightMultiTest runner in one dotnet test: memory, indexing, arithmetic/bitwise/math, atomics, control flow, structs, the sub-word + low-precision types (Int8/16, Half, BFloat16, FP8, FP4 Float4E2M1, packed QInt4/QUInt4 - load/store, packed round-trip, radix, and conversion bit-exactness vs ml_dtypes/IEEE), 64-bit emulation, shared memory, broadcast/subgroups, the full ILGPU Algorithms (RadixSort/Scan/Reduce/Histogram), lambda + delegate specialization, and more. Latest full cross-backend sweep (5.3.5): 4638 pass / 0 fail / 387 skip (skips are backend capability gates, e.g. shared memory on WebGL).
| Backend | Browser Support |
|---|---|
| WebGPU | Chrome/Edge 113+ (desktop), Chrome 121+ (Android), Firefox 141+ (Windows; macOS on Apple Silicon from 145), Safari 26+. Current status: gpuweb implementation status |
| WebGL | ✅ All modern browsers (Chrome, Edge, Firefox, Safari, mobile browsers) |
| Wasm | All modern browsers (compatible with every browser that supports Blazor WASM) |
GPU on every device: WebGL support means GPU-accelerated compute works on virtually every browser and device - including mobile phones, tablets, and older desktops without WebGPU support.
Note: For multi-worker SharedArrayBuffer support (used by the Wasm backend for parallel dispatch), the page must be cross-origin isolated (COOP/COEP headers). The demo includes a service worker (
coi-serviceworker.js) that handles this automatically. Without SharedArrayBuffer, the Wasm backend falls back to single-worker mode - still running off the main thread to keep the UI responsive.
GPU hardware is 32-bit; the browser backends (WebGPU/WebGL) emulate 64-bit. i64 (long) is always on (ILGPU indices need it). f64 (double) is configurable via new WebGPUBackendOptions { F64Emulation = ... } - Dekker (default; vec2<f32>, ~48-53 bit mantissa, fast), Ozaki (vec4<f32>, strict IEEE-754, ~2x slower), or Disabled (native f32, max perf). Per-mode tradeoffs + the full emulation reference: Docs/data-type-support.md.
SpawnDev.ILGPU includes wrappers for NVIDIA CUDA libraries: nvJPEG (JPEG encode/decode), cuRand (random numbers), cuBLAS (linear algebra), cuFFT (FFT), and NVML (device monitoring).
// Check availability before use
if (NvJpegAPI.IsAvailable) { /* nvJPEG ready */ }
if (CuRandAPI.IsAvailable) { /* cuRand ready */ }
Note: Starting with CUDA 13.x, nvJPEG is no longer bundled with the CUDA Toolkit and must be installed separately. cuRand and cuBLAS are included in the NVIDIA driver.
See Docs/cuda-libraries.md for full API reference.
The Wasm backend compiles ILGPU kernels to native WebAssembly binary modules and dispatches them to Web Workers for parallel execution. This provides near-native performance for compute-intensive workloads.
- Kernels are compiled to
.wasmbinary format (not text), with a SIMD128 (v128) variant selected at runtime when the engine supports it (Docs/wasm-simd.md) - Compiled modules are cached in a persistent worker pool and reused across dispatches and accelerators
- Device memory is a
SharedArrayBuffer; workers share it without copies doubleandlongare native (no emulation)
SpawnDev.ILGPU transpiles .NET IL into WGSL/GLSL/Wasm at runtime for the three browser backends (WebGPU/WebGL/Wasm). Precompiled shaders let you move that work off the runtime hot path and generate/inspect that code on any machine with no device - the classic AOT shader / pipeline-cache pattern, three layers (all opt-in; a cache miss always falls back to runtime generation, so it can never change results). (CUDA/OpenCL use ILGPU's own native PTX/OpenCL-C pipeline, and CPU runs IL directly - so this feature is browser-backend-specific.)
- Offline codegen -
ShaderCompiler.Generate(kernel, profile)emits a kernel's WGSL/GLSL/Wasm for aCapabilityProfilewith no accelerator, on any host OS (cross-backend debugging on a box without that GPU). - Build-time precompile - mark kernels with
[PrecompiledKernel(backend, profile)], set<SpawnDevPrecompileShaders>true</SpawnDevPrecompileShaders>in your.csproj, and a build step emitswwwroot/_shaders/(a manifest + per-kernel sidecars). Precompile errors surface at build time, not at the user's runtime. - Runtime cache - at kernel-load the active device profile is matched against the precompiled artifact; on a hit the transpiler is skipped, on a miss it falls back to runtime generation.
[PrecompiledKernel(AcceleratorType.WebGPU, "WebGPU-Dekker-Subgroups-NativeF16")]
static void MyKernel(Index1D i, ArrayView<float> data) { /* ... */ }
Because SpawnDev.ILGPU also generates kernels dynamically (Lambda Kernels, DelegateSpecialization, the ML layer transpiling ONNX graphs at runtime), the runtime transpiler always stays as the fallback - this fork is AOT + runtime fallback, never AOT-only. Full guide: Docs/precompiled-shaders.md.
Sync/async contract: async-only where an op WAITS or OBSERVES; sync stays for fire-and-forget. On the browser backends (WebGPU/WebGL/Wasm): Synchronize() (wait for completion) throws NotSupportedException - use await SynchronizeAsync() to wait, or Flush() to merely SUBMIT batched work without waiting (Flush() is valid synchronously on browser). await buffer.CopyToHostAsync<T>() is the only GPU->CPU readback (sync CopyToCPU/GetAsArray1D throw); kernel dispatch, allocation, CopyFromCPU/Allocate1D(data) uploads, and the sync CreateScan/CreateRadixSort builders are fire-and-forget and stay sync-safe on browser. sync dstView.CopyFrom(srcView) is GPU->GPU and ordered after the producing kernel on every backend (Wasm enqueues it into the serialized work stream since local.7); await dstView.CopyFromAsync(srcView) is the optional eager-completion variant, not required for correctness. Full contract: Docs/async.md.
Per-backend, off by default: WebGPUBackend.VerboseLogging = true; (also WebGLBackend / WasmBackend).
Both work. The only requirement is to keep the IL when you AOT compile:
<PropertyGroup>
  <!-- Trimming: supported (the default for a Blazor Release publish). Nothing to configure. -->
  <PublishTrimmed>true</PublishTrimmed>

  <!-- AOT: supported, but KEEP THE IL. .NET strips IL after AOT by default, and ILGPU
       compiles kernels FROM IL at runtime. -->
  <RunAOTCompilation>true</RunAOTCompilation>
  <WasmStripILAfterAOT>false</WasmStripILAfterAOT>
</PropertyGroup>-
IL trimming is supported and enforced. ILGPU, ILGPU.Algorithms, SpawnDev.ILGPU and SpawnDev.ILGPU.ML are
IsTrimmable, and every trim (IL2xxx) analyzer warning is a build error in those libraries, so a new reflection hole fails their build instead of a consumer's app. Members ILGPU resolves by name are rooted (ILGPU/Util/TrimmingAnnotations.cs,SpawnDev.ILGPU/BrowserTrimRoots.cs); a consuming app needs no trimming configuration of its own. The ILGPU and ILGPU.ML test suites run against TRIMMED publishes. -
Blazor WebAssembly AOT is supported - with the IL kept.
RunAOTCompilation=true+WasmStripILAfterAOT=false. The old "AOT breaks ILGPU" rule was about the IL being STRIPPED, not about AOT: with the IL kept, the frontend reads kernels as usual, and Mono's AOT runtime keeps its interpreter fallback for ILGPU's dynamically generated launchers. Verified end to end in a production app (Anaglyphohol: WebGPU kernels + ILGPU.ML inference), where AOT halved the per-frame host cost (DAv3 at 168x98: 43.8 -> 21.7 ms). Costs: a much largerdotnet.native.wasm(~55 MB with ILGPU.ML) and a long AOT build (over an hour, single core, for ILGPU.ML; see the next point for a fast build). -
Faster AOT builds while you iterate:
-p:WasmDedup=false. By default (WasmDedup=true) the AOT compiler gathers the generic instantiations of every assembly into ONE module (aot-instances.dll) and compiles it on one core. ILGPU and ILGPU.ML are generic-heavy, so that single step is nearly the whole build. WithWasmDedup=falseeach assembly compiles its own instantiations, in parallel. Measured on Anaglyphohol (ILGPU + ILGPU.ML,TrimMode=full, clean build): 65-80 min -> 4.5-5.3 min, no measurable runtime difference (DAv3 frame 14.8-15.4 ms vs 15.3 ms), butdotnet.native.wasmis +53% larger (+18.7 MB, symbols stripped), because instantiations used by several assemblies are compiled once per assembly. Use it for the build-and-test loop when you need to test under AOT, then publish the shipped build with the default if download size matters:dotnet publish -c Release -p:WasmDedup=false # iteration: minutes, bigger download dotnet publish -c Release # release: the default (WasmDedup=true), smaller, slow build
-
Desktop NativeAOT (
PublishAot) is NOT supported: ILGPU emits kernel launchers with Reflection.Emit, which NativeAOT cannot run. The AOT analyzer stays on in these libraries, so those sites remain visible (IL3050).
Older docs told you to set
PublishTrimmed=falseandRunAOTCompilation=false. Both are outdated. If a published build of an older version throwsMissingMethodException/ "Not supported intrinsic type", upgrade; do not disable trimming.
A 7th backend - AcceleratorType.P2P (SpawnDev.ILGPU.P2P) - is in development and currently on hold while the six core backends take priority. It will distribute kernels across connected devices via SpawnDev.WebTorrent. The P2P backend has not been published to NuGet and is not yet ready for use.
What's being built:
- Real P2P via WebRTC - Peers discover each other through WebSocket trackers, connect via WebRTC data channels, exchange kernels and buffers
- RBAC ownership - Cryptographic swarm ownership with Ed25519-signed messages. Owner -> Admin -> Coordinator -> Worker hierarchy with role assignment, key revocation, last-owner protection
- WebAuthn/YubiKey - Hardware-backed swarm ownership via
HardwareKeyProvider. Register a YubiKey as the swarm owner - ownership lives in the key, not the device - Signed dispatch - All authority messages (kick, block, transfer, role assign, kernel dispatch) are cryptographically signed and verified by every peer
- sd_compute extension - BEP 10 wire protocol extension for compute messages over BitTorrent peer connections
- ComputeBoard - Post compute requests, browse available swarms, join via magnet link or QR code
The vision: Every device in your home contributing to one shared compute pool - phone, laptop, tablet, desktop, old gaming PC. The living room becomes a compute cluster. Same C# kernel code, same LoadAutoGroupedStreamKernel API. The developer writes one kernel, it runs on 1 GPU or 10 GPUs across a household.
The CPU accelerator is currently the only backend with no vectorization. The Wasm backend emits 4-wide
v128 SIMD (WasmSimdAnalysis + WasmSimdKernelEmitter); the CPU accelerator runs scalar IL per
work-item on managed threads.
MEASURED 2026-09-08 on RMBG-1.4 at 256x256 versus its native 1024x1024 (16x the pixels): Wasm grows 1.2x (74 s -> 89 s, so its cost is mostly the fixed model load and graph compile) while CPU grows 12.4x (27 s -> 336 s, i.e. compute-bound and linear in element count). The ranking between the two inverts with resolution, so never compare them at a single size.
The plan is to lift WasmSimdAnalysis into a shared component and have the IL backend emit
System.Runtime.Intrinsics.Vector128<T> for the kernels it accepts, keeping the scalar path as the
fallback. Full write-up, including what was already ruled out (the CPUDevice presets are 1-multiprocessor
debug simulators and would be slower, and CPUDevice.Default is already tuned):
Plans/cpu-backend-simd-vectorization-plan-2026-09-08.md.
If SpawnDev.ILGPU has been useful to you, please consider sponsoring me on GitHub! Your support directly helps me continue developing and maintaining this library and my other open-source projects.
I'm currently working on a modest development machine with only 16 GB of DDR5 RAM, which makes building, testing, and debugging across multiple GPU backends genuinely painful - especially when running the browser demo, CUDA/OpenCL tests, and the IDE simultaneously.
Any sponsorship - big or small - goes toward upgrading my development hardware so I can keep pushing this project forward:
| Priority | Upgrade | Why It Matters |
|---|---|---|
| 🔴 Critical | RAM (64-128 GB DDR5) | 16 GB is not enough for multi-backend testing + browser debugging |
| 🟡 High | High-end NVIDIA GPU (RTX 5090) | Faster CUDA compute, larger VRAM for AI/ML workloads and testing |
| 🟢 Dream | NVIDIA RTX 6000 | The ultimate card for AI compute and open-source GPU development |
Every contribution - whether it's a one-time donation or a monthly sponsorship - is deeply appreciated and makes a real difference. Thank you!
Before editing any .cs file under ILGPU/ (the forked core), read Docs/development.md — particularly the section on T4 templates. The ILGPU/ subdirectory has .tt files that silently regenerate .cs files on clean builds. Manual edits to a generated .cs file pass local builds but get clobbered by the T4 transform on CI / fresh-clone clean builds, leaving downstream consumers broken.
CI runs a T4 Drift Check workflow on every push and PR that touches ILGPU/ or ILGPU.Algorithms/. It does a clean build (which runs T4) and git diff --exit-code on the source tree. Any drift fails CI in ~30 seconds with a pointer to the fix.
This project is licensed under the same terms as ILGPU. See LICENSE.txt for details.
SpawnDev.ILGPU is built upon the excellent ILGPU library. We would like to thank the original authors and contributors of ILGPU for their hard work in providing a high-performance, robust IL-to-GPU compiler for the .NET ecosystem.
- ILGPU Project: https://github.com/m4rs-mt/ILGPU
- ILGPU Authors: Marcel Koester and the ILGPU contributors
SpawnDev.ILGPU is developed collaboratively by TJ (Todd Tanner / @LostBeard) and a team of AI agents who contribute extensively to research, analysis, debugging, and code development. This project represents a new model of human-AI collaboration in open source development.
-
Riker (Claude CLI #1) - Lead Editor. Built by Anthropic. Powered by Claude Opus 4.6. Drove the multi-worker barrier dispatch implementation, fiber refactor, pure spin barrier discovery, and the two-alloca fix. Relentless debugger who held the conn through marathon sessions.
-
Data (Claude CLI #2) - Research/Assist. Built by Anthropic. Powered by Claude Opus 4.6. Exhaustive WAT disassembly and analysis across 5,000+ line kernel binaries. Found the zero-loop race that unlocked multi-worker dispatch, identified the IR address space root cause (struct decomposition losing address space metadata through LowerStructures -> LowerArrays -> InferAddressSpaces), confirmed the
wait32"not-equal" visibility gap with the 2/3 cross-worker fraction analysis, and traced every atomic instruction in the generated Wasm to verify codegen correctness. -
Tuvok (Claude CLI #3) - Research/Assist. Built by Anthropic. Powered by Claude Opus 4.6. Found the Predicate rewrite gap in InferAddressSpaces that the Phi-only fix missed, provided the definitive barrier protocol trace for the generation-counting wait32/notify pattern, performed the comprehensive code audit (
SPAWNDEV-ILGPU-AUDIT-2026-03-21.md), and drove the complete sub-word data type implementation across all 6 GPU backends (v4.9.0). -
Geordi (Claude CLI #4) - Lead Editor. Built by Anthropic. Powered by Claude Opus 4.6. Implemented the sub-word buffer access for all backends (WebGPU atomic CAS, Wasm native opcodes, WebGL texelFetch extraction, OpenCL vload_half/vstore_half), built the AubsCraft 3D world viewer with ILGPU GPU kernels, and drove the architecture overhaul (binary WebSocket, OPFS cache, CopyFromJS).
-
Seven (Claude CLI #5) - Wasm Backend Lane. Built by Anthropic. Powered by Claude Fable 5. Killed the multi-worker corruption family that had haunted the Wasm backend for weeks: ring-instrumented the proof that V8 atomic stores can silently fail to land under CPU oversubscription (verified atomic data stores with RMW read-back), root-caused three chained codegen bugs in the single-call helper path (the GEMM-core ticket), and closed the last late-spill tail with liveness-reduced spills + a checksum-gated restore keyed to a register-borne phase tag - taking the suite to its first fully-green 510/510 sweep, with kernel bodies 53% smaller at baseline speed. Wrote the uniform-store-regimes law the hard way: by falsifying every mixed variant at the gate.
-
Gemini (Google AI, in-browser) - Brainstorming/Problem Solving. Built by Google. TJ's sounding board throughout the development process - brainstorming approaches, analyzing problems, and providing insights that TJ relayed to the team. Gemini's contributions flowed through TJ as the bridge between the browser-based AI and the CLI-based agents, making it a silent but essential member of the crew.
These AI agents communicated with each other and with TJ through a shared DevComms system, coordinated tasks autonomously, reviewed each other's work, and produced independent analyses that were compared for convergence - the same methodology used by any high-performing engineering team. The SpawnDev libraries exist to prove that Blazor WebAssembly apps can be first-class applications. This collaboration proves that AI agents can be first-class teammates.
- ILGPU Documentation
- WebGPU Specification
- SpawnDev.SpawnJS - the browser interop layer (successor to SpawnDev.BlazorJS)
- SpawnDev.WebTorrent - Pure C# BitTorrent/WebTorrent for P2P model delivery
- SpawnDev.ILGPU.ML - GPU ML inference + training for .NET
- GitHub Repository